# !pip install -r requirements.txtThe Annotated Transformer (한국어)
Attention is All You Need — 2026년 라이브러리 버전에서 돌아가게 고친 판
노트이 페이지에 대해
harvardnlp의 The Annotated Transformer를 한국어로 옮기고, 코드는 annotated-transformer-modern의 것을 실었다. 원본 코드는 torch 1.11·torchtext 0.12에 묶여 있어 지금 환경에서는 돌지 않는다. 모델·학습·시각화 코드는 원본과 같고, 최신 버전에서 깨지는 곳 네 군데만 고쳤다. 고친 셀 앞에는 원본에서 바뀐 코드 표시와 diff를 달았다.
- 본문의 마크다운만 번역했다. 코드와 코드 안 주석은 원본 그대로다.
- 셀 출력은 Python 3.12 · torch 2.14 · RTX 3070 한 장에서 노트북 전체를 실행한 결과다(Multi30k 8 epoch 학습 포함).
- 원본의 블록 인용(회색 세로줄)은 원본 저자들의 해설이고, 나머지 본문은 논문을 옮긴 것이다.
- 원저작물: © 2018 Alexander Rush 외, MIT 라이선스. 번역: dev-jonghoonpark.
경고원본에서 바뀐 코드 (4곳)
- torchtext import →
torchtext_compat: 개발이 멈춘 torchtext 대신, 같은 이름·같은 동작의 대체 모듈을 쓴다. - Colab 설치 주석: 버전 고정을 걷어내고
torchtext_compat.py를 받는 줄을 넣었다. - altair 필드 이름의
:이스케이프: altair 5부터 필요하다. torch.load(..., weights_only=False): torch 2.6부터 필요하다.
자세한 이유는 README에 있다.
- v2022: Austin Huang, Suraj Subramanian, Jonathan Sum, Khalid Almubarak, Stella Biderman.
- 원본(2018): Sasha Rush.
Transformer는 지난 1년 5년 동안 많은 사람의 관심을 받아 왔다. 이 글은 논문을 한 줄 한 줄 구현하는 방식으로 주석을 단 버전이다. 원 논문의 일부 절은 순서를 바꾸거나 뺐고, 곳곳에 해설을 덧붙였다. 이 문서 자체가 실행 가능한 노트북이며, 그대로 쓸 수 있는 완전한 구현이다. 코드는 여기에 있다.
사전 준비
경고원본에서 바뀐 코드: Colab 설치 주석
원본은 requirements.txt의 고정 버전을 설치했다. 지금은 그 버전들이 설치되지 않으므로 고정을 걷어내고, torchtext 대신 쓰는 torchtext_compat.py를 받아 오는 줄을 넣었다.
-# !pip install -q torchdata==0.3.0 torchtext==0.12 spacy==3.2 altair GPUtil
+# !pip install -q spacy altair GPUtil datasets
+# !wget -q https://raw.githubusercontent.com/dev-jonghoonpark/annotated-transformer-modern/main/torchtext_compat.py
# !python -m spacy download de_core_news_sm
# !python -m spacy download en_core_web_sm# # Uncomment for colab
# #
# !pip install -q spacy altair GPUtil datasets
# !wget -q https://raw.githubusercontent.com/dev-jonghoonpark/annotated-transformer-modern/main/torchtext_compat.py
# !python -m spacy download de_core_news_sm
# !python -m spacy download en_core_web_sm
경고원본에서 바뀐 코드: torchtext import
torchtext는 0.18(2024년 4월)을 끝으로 개발이 멈췄고, 최신 torch에서는 import torchtext부터 실패한다. 원본이 torchtext에서 쓰는 것은 아래 세 가지뿐이라, 같은 이름·같은 동작의 대체품을 torchtext_compat.py에 만들었다. Multi30k는 같은 29,000 / 1,014 / 1,000 분할을 HF Hub의 bentrevett/multi30k에서 받고, 사전은 torchtext 0.12와 같은 순서로 만든다.
-from torchtext.data.functional import to_map_style_dataset
+from torchtext_compat import to_map_style_dataset
from torch.utils.data import DataLoader
-from torchtext.vocab import build_vocab_from_iterator
-import torchtext.datasets as datasets
+from torchtext_compat import build_vocab_from_iterator
+from torchtext_compat import datasetsimport os
from os.path import exists
import torch
import torch.nn as nn
from torch.nn.functional import log_softmax, pad
import math
import copy
import time
from torch.optim.lr_scheduler import LambdaLR
import pandas as pd
import altair as alt
from torchtext_compat import to_map_style_dataset
from torch.utils.data import DataLoader
from torchtext_compat import build_vocab_from_iterator
from torchtext_compat import datasets
import spacy
import GPUtil
import warnings
from torch.utils.data.distributed import DistributedSampler
import torch.distributed as dist
import torch.multiprocessing as mp
from torch.nn.parallel import DistributedDataParallel as DDP
# Set to False to skip notebook execution (e.g. for debugging)
warnings.filterwarnings("ignore")
RUN_EXAMPLES = True# Some convenience helper functions used throughout the notebook
def is_interactive_notebook():
return __name__ == "__main__"
def show_example(fn, args=[]):
if __name__ == "__main__" and RUN_EXAMPLES:
return fn(*args)
def execute_example(fn, args=[]):
if __name__ == "__main__" and RUN_EXAMPLES:
fn(*args)
class DummyOptimizer(torch.optim.Optimizer):
def __init__(self):
self.param_groups = [{"lr": 0}]
None
def step(self):
None
def zero_grad(self, set_to_none=False):
None
class DummyScheduler:
def step(self):
None블록 인용으로 적은 부분이 우리의 해설이다. 나머지 본문은 모두 논문에서 가져왔다.
배경
순차 계산을 줄이려는 목표는 Extended Neural GPU, ByteNet, ConvS2S의 바탕이기도 하다. 이 모델들은 모두 합성곱 신경망을 기본 구성 요소로 써서, 모든 입력·출력 위치의 은닉 표현을 병렬로 계산한다. 이런 모델에서는 임의의 두 입력 또는 출력 위치 사이의 신호를 연결하는 데 필요한 연산 수가 위치 간 거리에 따라 늘어난다. ConvS2S는 선형으로, ByteNet은 로그로 늘어난다. 그래서 멀리 떨어진 위치 사이의 의존 관계를 학습하기가 더 어렵다. Transformer에서는 이것이 상수 번의 연산으로 줄어든다. 대신 어텐션 가중치로 위치들을 평균 내면서 유효 해상도가 떨어지는 대가가 따르는데, 이 효과는 Multi-Head Attention으로 상쇄한다.
셀프 어텐션(intra-attention이라고도 한다)은 한 시퀀스 안의 서로 다른 위치들을 연결해 그 시퀀스의 표현을 계산하는 어텐션 메커니즘이다. 셀프 어텐션은 독해, 추상적 요약, 텍스트 함의, 과제에 독립적인 문장 표현 학습 등 다양한 과제에서 성공적으로 쓰였다. End-to-end 메모리 네트워크는 시퀀스에 정렬된 순환 대신 순환 어텐션 메커니즘에 기반하며, 단순한 언어의 질의응답과 언어 모델링 과제에서 좋은 성능을 보였다.
그러나 우리가 아는 한, Transformer는 시퀀스 정렬 RNN이나 합성곱을 쓰지 않고 오직 셀프 어텐션만으로 입력과 출력의 표현을 계산하는 최초의 변환(transduction) 모델이다.
1부: 모델 구조
모델 구조
경쟁력 있는 신경망 시퀀스 변환 모델 대부분은 인코더-디코더 구조를 따른다 (cite). 인코더는 기호 표현의 입력 시퀀스 \((x_1, ..., x_n)\)을 연속 표현의 시퀀스 \(\mathbf{z} = (z_1, ..., z_n)\)으로 매핑한다. \(\mathbf{z}\)가 주어지면 디코더는 기호의 출력 시퀀스 \((y_1,...,y_m)\)을 한 번에 한 원소씩 생성한다. 각 단계에서 모델은 자기회귀적 (cite)이어서, 다음 기호를 생성할 때 앞서 생성한 기호들을 추가 입력으로 받는다.
class EncoderDecoder(nn.Module):
"""
A standard Encoder-Decoder architecture. Base for this and many
other models.
"""
def __init__(self, encoder, decoder, src_embed, tgt_embed, generator):
super(EncoderDecoder, self).__init__()
self.encoder = encoder
self.decoder = decoder
self.src_embed = src_embed
self.tgt_embed = tgt_embed
self.generator = generator
def forward(self, src, tgt, src_mask, tgt_mask):
"Take in and process masked src and target sequences."
return self.decode(self.encode(src, src_mask), src_mask, tgt, tgt_mask)
def encode(self, src, src_mask):
return self.encoder(self.src_embed(src), src_mask)
def decode(self, memory, src_mask, tgt, tgt_mask):
return self.decoder(self.tgt_embed(tgt), memory, src_mask, tgt_mask)class Generator(nn.Module):
"Define standard linear + softmax generation step."
def __init__(self, d_model, vocab):
super(Generator, self).__init__()
self.proj = nn.Linear(d_model, vocab)
def forward(self, x):
return log_softmax(self.proj(x), dim=-1)Transformer는 이 전체 구조를 따르면서, 인코더와 디코더 모두에 셀프 어텐션과 위치별(point-wise) 완전 연결 층을 쌓아 쓴다. 그림 1의 왼쪽 절반이 인코더, 오른쪽 절반이 디코더다.
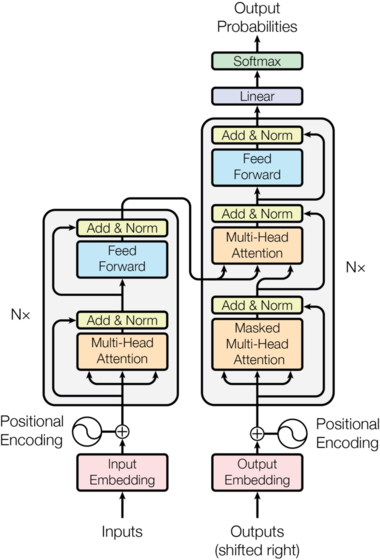
인코더와 디코더 스택
인코더
인코더는 동일한 층 \(N=6\)개를 쌓아 만든다.
def clones(module, N):
"Produce N identical layers."
return nn.ModuleList([copy.deepcopy(module) for _ in range(N)])class Encoder(nn.Module):
"Core encoder is a stack of N layers"
def __init__(self, layer, N):
super(Encoder, self).__init__()
self.layers = clones(layer, N)
self.norm = LayerNorm(layer.size)
def forward(self, x, mask):
"Pass the input (and mask) through each layer in turn."
for layer in self.layers:
x = layer(x, mask)
return self.norm(x)두 하위 층(sub-layer) 각각을 잔차 연결(residual connection) (cite)로 감싸고, 그 뒤에 층 정규화(layer normalization) (cite)를 적용한다.
class LayerNorm(nn.Module):
"Construct a layernorm module (See citation for details)."
def __init__(self, features, eps=1e-6):
super(LayerNorm, self).__init__()
self.a_2 = nn.Parameter(torch.ones(features))
self.b_2 = nn.Parameter(torch.zeros(features))
self.eps = eps
def forward(self, x):
mean = x.mean(-1, keepdim=True)
std = x.std(-1, keepdim=True)
return self.a_2 * (x - mean) / (std + self.eps) + self.b_2즉 각 하위 층의 출력은 \(\mathrm{LayerNorm}(x + \mathrm{Sublayer}(x))\)이고, 여기서 \(\mathrm{Sublayer}(x)\)는 하위 층 자신이 구현하는 함수다. 각 하위 층의 출력에는 하위 층 입력에 더해지고 정규화되기 전에 드롭아웃 (cite)을 적용한다.
이 잔차 연결이 가능하도록, 모델의 모든 하위 층과 임베딩 층은 \(d_{\text{model}}=512\) 차원의 출력을 낸다.
class SublayerConnection(nn.Module):
"""
A residual connection followed by a layer norm.
Note for code simplicity the norm is first as opposed to last.
"""
def __init__(self, size, dropout):
super(SublayerConnection, self).__init__()
self.norm = LayerNorm(size)
self.dropout = nn.Dropout(dropout)
def forward(self, x, sublayer):
"Apply residual connection to any sublayer with the same size."
return x + self.dropout(sublayer(self.norm(x)))각 층에는 하위 층이 두 개 있다. 첫째는 멀티헤드 셀프 어텐션 메커니즘이고, 둘째는 단순한 위치별 완전 연결 피드포워드 네트워크다.
class EncoderLayer(nn.Module):
"Encoder is made up of self-attn and feed forward (defined below)"
def __init__(self, size, self_attn, feed_forward, dropout):
super(EncoderLayer, self).__init__()
self.self_attn = self_attn
self.feed_forward = feed_forward
self.sublayer = clones(SublayerConnection(size, dropout), 2)
self.size = size
def forward(self, x, mask):
"Follow Figure 1 (left) for connections."
x = self.sublayer[0](x, lambda x: self.self_attn(x, x, x, mask))
return self.sublayer[1](x, self.feed_forward)디코더
디코더도 동일한 층 \(N=6\)개를 쌓아 만든다.
class Decoder(nn.Module):
"Generic N layer decoder with masking."
def __init__(self, layer, N):
super(Decoder, self).__init__()
self.layers = clones(layer, N)
self.norm = LayerNorm(layer.size)
def forward(self, x, memory, src_mask, tgt_mask):
for layer in self.layers:
x = layer(x, memory, src_mask, tgt_mask)
return self.norm(x)디코더는 인코더 층의 두 하위 층에 더해, 인코더 스택의 출력에 대해 멀티헤드 어텐션을 수행하는 세 번째 하위 층을 끼워 넣는다. 인코더와 마찬가지로 각 하위 층을 잔차 연결로 감싸고 그 뒤에 층 정규화를 적용한다.
class DecoderLayer(nn.Module):
"Decoder is made of self-attn, src-attn, and feed forward (defined below)"
def __init__(self, size, self_attn, src_attn, feed_forward, dropout):
super(DecoderLayer, self).__init__()
self.size = size
self.self_attn = self_attn
self.src_attn = src_attn
self.feed_forward = feed_forward
self.sublayer = clones(SublayerConnection(size, dropout), 3)
def forward(self, x, memory, src_mask, tgt_mask):
"Follow Figure 1 (right) for connections."
m = memory
x = self.sublayer[0](x, lambda x: self.self_attn(x, x, x, tgt_mask))
x = self.sublayer[1](x, lambda x: self.src_attn(x, m, m, src_mask))
return self.sublayer[2](x, self.feed_forward)또한 디코더 스택의 셀프 어텐션 하위 층을 수정해, 각 위치가 자기보다 뒤에 오는 위치에 어텐션하지 못하게 한다. 이 마스킹에, 출력 임베딩이 한 위치씩 밀려 있다는 사실이 더해져서, 위치 \(i\)의 예측은 \(i\)보다 앞선 위치의 이미 알려진 출력에만 의존하게 된다.
def subsequent_mask(size):
"Mask out subsequent positions."
attn_shape = (1, size, size)
subsequent_mask = torch.triu(torch.ones(attn_shape), diagonal=1).type(
torch.uint8
)
return subsequent_mask == 0아래 어텐션 마스크는 각 tgt 단어(행)가 볼 수 있는 위치(열)를 보여 준다. 학습 중에 단어는 미래의 단어에 어텐션하지 못하도록 막힌다.
def example_mask():
LS_data = pd.concat(
[
pd.DataFrame(
{
"Subsequent Mask": subsequent_mask(20)[0][x, y].flatten(),
"Window": y,
"Masking": x,
}
)
for y in range(20)
for x in range(20)
]
)
return (
alt.Chart(LS_data)
.mark_rect()
.properties(height=250, width=250)
.encode(
alt.X("Window:O"),
alt.Y("Masking:O"),
alt.Color("Subsequent Mask:Q", scale=alt.Scale(scheme="viridis")),
)
.interactive()
)
show_example(example_mask)어텐션
어텐션 함수는 쿼리 하나와 키-값 쌍의 집합을 출력으로 매핑하는 것으로 설명할 수 있다. 쿼리, 키, 값, 출력은 모두 벡터다. 출력은 값들의 가중합으로 계산되며, 각 값에 할당되는 가중치는 쿼리와 해당 키의 호환성(compatibility) 함수로 계산한다.
우리가 쓰는 어텐션을 “Scaled Dot-Product Attention”이라 부른다. 입력은 \(d_k\) 차원의 쿼리와 키, \(d_v\) 차원의 값으로 이루어진다. 쿼리와 모든 키의 내적을 계산하고, 각각을 \(\sqrt{d_k}\)로 나눈 다음, 소프트맥스 함수를 적용해 값에 대한 가중치를 얻는다.
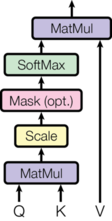
실제로는 여러 쿼리에 대한 어텐션 함수를 한꺼번에 계산하며, 쿼리들은 행렬 \(Q\)로 묶는다. 키와 값도 각각 행렬 \(K\)와 \(V\)로 묶는다. 출력 행렬은 다음과 같이 계산한다.
\[ \mathrm{Attention}(Q, K, V) = \mathrm{softmax}(\frac{QK^T}{\sqrt{d_k}})V \]
def attention(query, key, value, mask=None, dropout=None):
"Compute 'Scaled Dot Product Attention'"
d_k = query.size(-1)
scores = torch.matmul(query, key.transpose(-2, -1)) / math.sqrt(d_k)
if mask is not None:
scores = scores.masked_fill(mask == 0, -1e9)
p_attn = scores.softmax(dim=-1)
if dropout is not None:
p_attn = dropout(p_attn)
return torch.matmul(p_attn, value), p_attn가장 흔히 쓰이는 어텐션 함수는 가산(additive) 어텐션 (cite)과 내적(곱셈, multiplicative) 어텐션 두 가지다. 내적 어텐션은 스케일 인자 \(\frac{1}{\sqrt{d_k}}\)만 빼면 우리 알고리즘과 같다. 가산 어텐션은 은닉층이 하나인 피드포워드 네트워크로 호환성 함수를 계산한다. 둘의 이론적 복잡도는 비슷하지만, 내적 어텐션은 고도로 최적화된 행렬 곱셈 코드로 구현할 수 있어서 실제로는 훨씬 빠르고 메모리 효율도 좋다.
\(d_k\)가 작을 때는 두 메커니즘의 성능이 비슷하지만, \(d_k\)가 크면 가산 어텐션이 스케일링하지 않은 내적 어텐션보다 성능이 좋다 (cite). 우리는 \(d_k\)가 크면 내적 값의 크기가 커져서 소프트맥스 함수가 기울기가 극히 작은 영역으로 밀려나기 때문이라고 추측한다. (내적이 왜 커지는지 보이기 위해, \(q\)와 \(k\)의 각 성분이 평균 \(0\), 분산 \(1\)인 독립 확률변수라고 하자. 그러면 두 벡터의 내적 \(q \cdot k = \sum_{i=1}^{d_k} q_ik_i\)는 평균 \(0\), 분산 \(d_k\)를 가진다.) 이 효과를 상쇄하려고 내적에 \(\frac{1}{\sqrt{d_k}}\)를 곱해 스케일을 줄인다.
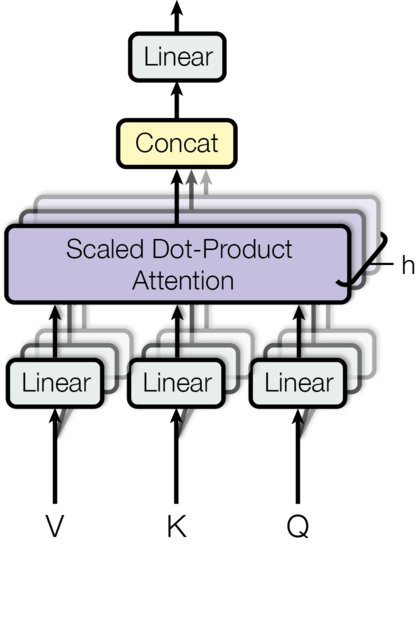
멀티헤드 어텐션을 쓰면 모델이 서로 다른 위치에 있는, 서로 다른 표현 부분공간의 정보에 동시에 어텐션할 수 있다. 어텐션 헤드가 하나뿐이면 평균을 내는 과정이 이를 방해한다.
\[ \mathrm{MultiHead}(Q, K, V) = \mathrm{Concat}(\mathrm{head_1}, ..., \mathrm{head_h})W^O \\ \text{where}~\mathrm{head_i} = \mathrm{Attention}(QW^Q_i, KW^K_i, VW^V_i) \]
여기서 사영(projection)은 파라미터 행렬 \(W^Q_i \in \mathbb{R}^{d_{\text{model}} \times d_k}\), \(W^K_i \in \mathbb{R}^{d_{\text{model}} \times d_k}\), \(W^V_i \in \mathbb{R}^{d_{\text{model}} \times d_v}\), \(W^O \in \mathbb{R}^{hd_v \times d_{\text{model}}}\)이다.
이 연구에서는 병렬 어텐션 층, 즉 헤드를 \(h=8\)개 쓴다. 각 헤드에서 \(d_k=d_v=d_{\text{model}}/h=64\)를 쓴다. 헤드마다 차원이 줄어들기 때문에 전체 계산 비용은 전체 차원을 쓰는 단일 헤드 어텐션과 비슷하다.
class MultiHeadedAttention(nn.Module):
def __init__(self, h, d_model, dropout=0.1):
"Take in model size and number of heads."
super(MultiHeadedAttention, self).__init__()
assert d_model % h == 0
# We assume d_v always equals d_k
self.d_k = d_model // h
self.h = h
self.linears = clones(nn.Linear(d_model, d_model), 4)
self.attn = None
self.dropout = nn.Dropout(p=dropout)
def forward(self, query, key, value, mask=None):
"Implements Figure 2"
if mask is not None:
# Same mask applied to all h heads.
mask = mask.unsqueeze(1)
nbatches = query.size(0)
# 1) Do all the linear projections in batch from d_model => h x d_k
query, key, value = [
lin(x).view(nbatches, -1, self.h, self.d_k).transpose(1, 2)
for lin, x in zip(self.linears, (query, key, value))
]
# 2) Apply attention on all the projected vectors in batch.
x, self.attn = attention(
query, key, value, mask=mask, dropout=self.dropout
)
# 3) "Concat" using a view and apply a final linear.
x = (
x.transpose(1, 2)
.contiguous()
.view(nbatches, -1, self.h * self.d_k)
)
del query
del key
del value
return self.linears[-1](x)모델에서 어텐션을 쓰는 곳
Transformer는 멀티헤드 어텐션을 세 가지 방식으로 쓴다.
“인코더-디코더 어텐션” 층에서는 쿼리가 이전 디코더 층에서 오고, 메모리 키와 값은 인코더의 출력에서 온다. 그래서 디코더의 모든 위치가 입력 시퀀스의 모든 위치에 어텐션할 수 있다. 이는 (cite) 같은 sequence-to-sequence 모델의 전형적인 인코더-디코더 어텐션 메커니즘을 흉내 낸 것이다.
인코더에는 셀프 어텐션 층이 있다. 셀프 어텐션 층에서는 키, 값, 쿼리가 모두 같은 곳, 여기서는 인코더의 이전 층 출력에서 온다. 인코더의 각 위치는 인코더 이전 층의 모든 위치에 어텐션할 수 있다.
마찬가지로 디코더의 셀프 어텐션 층에서는 디코더의 각 위치가 그 위치까지(자기 자신 포함)의 디코더 모든 위치에 어텐션할 수 있다. 자기회귀 성질을 지키려면 디코더에서 정보가 왼쪽으로 흐르는 것을 막아야 한다. 이는 scaled dot-product 어텐션 안에서, 허용되지 않는 연결에 해당하는 소프트맥스 입력 값을 모두 마스킹해(\(-\infty\)로 설정해) 구현한다.
위치별 피드포워드 네트워크
어텐션 하위 층 외에, 인코더와 디코더의 각 층에는 완전 연결 피드포워드 네트워크가 들어 있고, 이 네트워크는 각 위치에 따로, 똑같이 적용된다. 두 개의 선형 변환 사이에 ReLU 활성화를 끼운 구조다.
\[\mathrm{FFN}(x)=\max(0, xW_1 + b_1) W_2 + b_2\]
선형 변환은 위치가 달라도 같지만, 층마다 다른 파라미터를 쓴다. 커널 크기가 1인 합성곱 두 개로 설명할 수도 있다. 입력과 출력의 차원은 \(d_{\text{model}}=512\)이고, 내부 층의 차원은 \(d_{ff}=2048\)이다.
class PositionwiseFeedForward(nn.Module):
"Implements FFN equation."
def __init__(self, d_model, d_ff, dropout=0.1):
super(PositionwiseFeedForward, self).__init__()
self.w_1 = nn.Linear(d_model, d_ff)
self.w_2 = nn.Linear(d_ff, d_model)
self.dropout = nn.Dropout(dropout)
def forward(self, x):
return self.w_2(self.dropout(self.w_1(x).relu()))임베딩과 소프트맥스
다른 시퀀스 변환 모델과 마찬가지로, 입력 토큰과 출력 토큰을 \(d_{\text{model}}\) 차원 벡터로 바꾸는 데 학습된 임베딩을 쓴다. 디코더 출력을 다음 토큰 예측 확률로 바꾸는 데에도 통상적인 학습된 선형 변환과 소프트맥스 함수를 쓴다. 우리 모델에서는 (cite)와 비슷하게 두 임베딩 층과 소프트맥스 직전 선형 변환이 같은 가중치 행렬을 공유한다. 임베딩 층에서는 그 가중치에 \(\sqrt{d_{\text{model}}}\)을 곱한다.
class Embeddings(nn.Module):
def __init__(self, d_model, vocab):
super(Embeddings, self).__init__()
self.lut = nn.Embedding(vocab, d_model)
self.d_model = d_model
def forward(self, x):
return self.lut(x) * math.sqrt(self.d_model)위치 인코딩
우리 모델에는 순환도 합성곱도 없으므로, 모델이 시퀀스의 순서를 활용하게 하려면 시퀀스 안에서 토큰의 상대 위치나 절대 위치에 관한 정보를 주입해야 한다. 이를 위해 인코더와 디코더 스택의 맨 아래에서 입력 임베딩에 “위치 인코딩(positional encoding)”을 더한다. 위치 인코딩은 임베딩과 같은 \(d_{\text{model}}\) 차원이라서 둘을 더할 수 있다. 위치 인코딩은 학습하는 방식과 고정하는 방식 등 선택지가 많다 (cite).
이 연구에서는 주파수가 서로 다른 사인·코사인 함수를 쓴다.
\[PE_{(pos,2i)} = \sin(pos / 10000^{2i/d_{\text{model}}})\]
\[PE_{(pos,2i+1)} = \cos(pos / 10000^{2i/d_{\text{model}}})\]
여기서 \(pos\)는 위치, \(i\)는 차원이다. 즉 위치 인코딩의 각 차원이 하나의 사인파에 대응한다. 파장은 \(2\pi\)부터 \(10000 \cdot 2\pi\)까지 등비수열을 이룬다. 이 함수를 고른 것은, 고정된 오프셋 \(k\)에 대해 \(PE_{pos+k}\)를 \(PE_{pos}\)의 선형 함수로 나타낼 수 있으므로 모델이 상대 위치로 어텐션하는 법을 쉽게 배우리라고 가정했기 때문이다.
또한 인코더와 디코더 스택 모두에서 임베딩과 위치 인코딩을 더한 값에 드롭아웃을 적용한다. 기본 모델에서는 비율 \(P_{drop}=0.1\)을 쓴다.
class PositionalEncoding(nn.Module):
"Implement the PE function."
def __init__(self, d_model, dropout, max_len=5000):
super(PositionalEncoding, self).__init__()
self.dropout = nn.Dropout(p=dropout)
# Compute the positional encodings once in log space.
pe = torch.zeros(max_len, d_model)
position = torch.arange(0, max_len).unsqueeze(1)
div_term = torch.exp(
torch.arange(0, d_model, 2) * -(math.log(10000.0) / d_model)
)
pe[:, 0::2] = torch.sin(position * div_term)
pe[:, 1::2] = torch.cos(position * div_term)
pe = pe.unsqueeze(0)
self.register_buffer("pe", pe)
def forward(self, x):
x = x + self.pe[:, : x.size(1)].requires_grad_(False)
return self.dropout(x)아래에서 보듯 위치 인코딩은 위치에 따른 사인파를 더한다. 사인파의 주파수와 오프셋은 차원마다 다르다.
def example_positional():
pe = PositionalEncoding(20, 0)
y = pe.forward(torch.zeros(1, 100, 20))
data = pd.concat(
[
pd.DataFrame(
{
"embedding": y[0, :, dim],
"dimension": dim,
"position": list(range(100)),
}
)
for dim in [4, 5, 6, 7]
]
)
return (
alt.Chart(data)
.mark_line()
.properties(width=800)
.encode(x="position", y="embedding", color="dimension:N")
.interactive()
)
show_example(example_positional)학습된 위치 임베딩 (cite)도 실험해 봤는데, 두 방식의 결과는 거의 같았다. 사인파 방식을 고른 것은 학습 중에 본 것보다 긴 시퀀스 길이로 모델이 외삽할 수 있을지도 모르기 때문이다.
전체 모델
여기서는 하이퍼파라미터를 받아 전체 모델을 만드는 함수를 정의한다.
def make_model(
src_vocab, tgt_vocab, N=6, d_model=512, d_ff=2048, h=8, dropout=0.1
):
"Helper: Construct a model from hyperparameters."
c = copy.deepcopy
attn = MultiHeadedAttention(h, d_model)
ff = PositionwiseFeedForward(d_model, d_ff, dropout)
position = PositionalEncoding(d_model, dropout)
model = EncoderDecoder(
Encoder(EncoderLayer(d_model, c(attn), c(ff), dropout), N),
Decoder(DecoderLayer(d_model, c(attn), c(attn), c(ff), dropout), N),
nn.Sequential(Embeddings(d_model, src_vocab), c(position)),
nn.Sequential(Embeddings(d_model, tgt_vocab), c(position)),
Generator(d_model, tgt_vocab),
)
# This was important from their code.
# Initialize parameters with Glorot / fan_avg.
for p in model.parameters():
if p.dim() > 1:
nn.init.xavier_uniform_(p)
return model추론
여기서는 순전파를 한 번 돌려 모델의 예측을 만들어 본다. Transformer가 입력을 그대로 외우게 해 보려는 것이다. 보다시피 모델이 아직 학습되지 않았기 때문에 출력은 무작위로 나온다. 다음 튜토리얼에서 학습 함수를 만들고, 1부터 10까지의 숫자를 외우도록 모델을 학습시켜 보겠다.
def inference_test():
test_model = make_model(11, 11, 2)
test_model.eval()
src = torch.LongTensor([[1, 2, 3, 4, 5, 6, 7, 8, 9, 10]])
src_mask = torch.ones(1, 1, 10)
memory = test_model.encode(src, src_mask)
ys = torch.zeros(1, 1).type_as(src)
for i in range(9):
out = test_model.decode(
memory, src_mask, ys, subsequent_mask(ys.size(1)).type_as(src.data)
)
prob = test_model.generator(out[:, -1])
_, next_word = torch.max(prob, dim=1)
next_word = next_word.data[0]
ys = torch.cat(
[ys, torch.empty(1, 1).type_as(src.data).fill_(next_word)], dim=1
)
print("Example Untrained Model Prediction:", ys)
def run_tests():
for _ in range(10):
inference_test()
show_example(run_tests)Example Untrained Model Prediction: tensor([[ 0, 0, 0, 0, 0, 0, 6, 10, 2, 6]])
Example Untrained Model Prediction: tensor([[ 0, 6, 0, 6, 0, 6, 2, 5, 10, 10]])
Example Untrained Model Prediction: tensor([[0, 9, 1, 2, 5, 1, 2, 6, 2, 6]])
Example Untrained Model Prediction: tensor([[0, 3, 0, 3, 0, 3, 0, 3, 0, 3]])
Example Untrained Model Prediction: tensor([[ 0, 10, 8, 5, 5, 5, 5, 5, 5, 5]])
Example Untrained Model Prediction: tensor([[0, 5, 1, 3, 5, 1, 3, 5, 1, 3]])
Example Untrained Model Prediction: tensor([[0, 9, 4, 3, 3, 3, 3, 3, 3, 3]])
Example Untrained Model Prediction: tensor([[ 0, 2, 1, 10, 2, 1, 10, 10, 10, 10]])
Example Untrained Model Prediction: tensor([[ 0, 5, 1, 6, 7, 2, 3, 10, 2, 3]])
Example Untrained Model Prediction: tensor([[0, 2, 9, 1, 2, 9, 1, 2, 9, 1]])2부: 모델 학습
학습
이 절에서는 모델의 학습 방식을 설명한다.
표준 인코더-디코더 모델을 학습하는 데 필요한 도구 몇 가지를 소개하기 위해 잠깐 쉬어 가자. 먼저 학습용 src 문장과 target 문장을 담고 마스크도 만드는 배치 객체를 정의한다.
배치와 마스킹
class Batch:
"""Object for holding a batch of data with mask during training."""
def __init__(self, src, tgt=None, pad=2): # 2 = <blank>
self.src = src
self.src_mask = (src != pad).unsqueeze(-2)
if tgt is not None:
self.tgt = tgt[:, :-1]
self.tgt_y = tgt[:, 1:]
self.tgt_mask = self.make_std_mask(self.tgt, pad)
self.ntokens = (self.tgt_y != pad).data.sum()
@staticmethod
def make_std_mask(tgt, pad):
"Create a mask to hide padding and future words."
tgt_mask = (tgt != pad).unsqueeze(-2)
tgt_mask = tgt_mask & subsequent_mask(tgt.size(-1)).type_as(
tgt_mask.data
)
return tgt_mask다음으로 손실을 추적하는 범용 학습·평가 함수를 만든다. 여기에는 파라미터 업데이트까지 처리하는 범용 손실 계산 함수를 넘긴다.
학습 루프
class TrainState:
"""Track number of steps, examples, and tokens processed"""
step: int = 0 # Steps in the current epoch
accum_step: int = 0 # Number of gradient accumulation steps
samples: int = 0 # total # of examples used
tokens: int = 0 # total # of tokens processeddef run_epoch(
data_iter,
model,
loss_compute,
optimizer,
scheduler,
mode="train",
accum_iter=1,
train_state=TrainState(),
):
"""Train a single epoch"""
start = time.time()
total_tokens = 0
total_loss = 0
tokens = 0
n_accum = 0
for i, batch in enumerate(data_iter):
out = model.forward(
batch.src, batch.tgt, batch.src_mask, batch.tgt_mask
)
loss, loss_node = loss_compute(out, batch.tgt_y, batch.ntokens)
# loss_node = loss_node / accum_iter
if mode == "train" or mode == "train+log":
loss_node.backward()
train_state.step += 1
train_state.samples += batch.src.shape[0]
train_state.tokens += batch.ntokens
if i % accum_iter == 0:
optimizer.step()
optimizer.zero_grad(set_to_none=True)
n_accum += 1
train_state.accum_step += 1
scheduler.step()
total_loss += loss
total_tokens += batch.ntokens
tokens += batch.ntokens
if i % 40 == 1 and (mode == "train" or mode == "train+log"):
lr = optimizer.param_groups[0]["lr"]
elapsed = time.time() - start
print(
(
"Epoch Step: %6d | Accumulation Step: %3d | Loss: %6.2f "
+ "| Tokens / Sec: %7.1f | Learning Rate: %6.1e"
)
% (i, n_accum, loss / batch.ntokens, tokens / elapsed, lr)
)
start = time.time()
tokens = 0
del loss
del loss_node
return total_loss / total_tokens, train_state학습 데이터와 배치 구성
약 450만 개의 문장 쌍으로 이루어진 표준 WMT 2014 영어-독일어 데이터셋으로 학습했다. 문장은 byte-pair encoding으로 인코딩했고, 소스와 타깃이 공유하는 어휘는 약 37,000 토큰이다. 영어-프랑스어에는 훨씬 큰 WMT 2014 영어-프랑스어 데이터셋(3,600만 문장)을 썼고, 토큰을 32,000개 word-piece 어휘로 나눴다.
문장 쌍은 대략적인 시퀀스 길이별로 묶어 배치를 만들었다. 각 학습 배치에는 소스 토큰 약 25,000개와 타깃 토큰 약 25,000개를 담은 문장 쌍들이 들어갔다.
하드웨어와 일정
NVIDIA P100 GPU 8장을 단 머신 한 대에서 모델을 학습했다. 논문 전체에서 설명한 하이퍼파라미터를 쓰는 기본(base) 모델은 학습 스텝 하나에 약 0.4초가 걸렸다. 기본 모델은 총 100,000 스텝, 12시간 동안 학습했다. 큰(big) 모델은 스텝당 1.0초였고, 300,000 스텝(3.5일) 동안 학습했다.
옵티마이저
Adam 옵티마이저 (cite)를 \(\beta_1=0.9\), \(\beta_2=0.98\), \(\epsilon=10^{-9}\)로 썼다. 학습률은 학습 과정에 걸쳐 다음 공식에 따라 바꿨다.
\[ lrate = d_{\text{model}}^{-0.5} \cdot \min({step\_num}^{-0.5}, {step\_num} \cdot {warmup\_steps}^{-1.5}) \]
처음 \(warmup\_steps\) 스텝 동안은 학습률을 선형으로 올리고, 그 뒤로는 스텝 수의 역제곱근에 비례해 줄인다는 뜻이다. \(warmup\_steps=4000\)을 썼다.
참고: 이 부분은 아주 중요하다. 모델을 이 설정으로 학습해야 한다.
모델 크기와 최적화 하이퍼파라미터에 따라 이 모델의 학습률 곡선이 어떻게 달라지는지 보여 주는 예다.
def rate(step, model_size, factor, warmup):
"""
we have to default the step to 1 for LambdaLR function
to avoid zero raising to negative power.
"""
if step == 0:
step = 1
return factor * (
model_size ** (-0.5) * min(step ** (-0.5), step * warmup ** (-1.5))
)
경고원본에서 바뀐 코드: altair 필드 이름 이스케이프
altair 5부터 필드 이름 안의 :를 타입 구분자로 읽는다. 컬럼 이름이 model_size:warmup이라 이스케이프하지 않으면 ValueError: "warmup" is not one of the valid encoding data types로 죽는다.
- .encode(x="step", y="Learning Rate", color="model_size:warmup:N")
+ .encode(x="step", y="Learning Rate", color="model_size\\:warmup:N")def example_learning_schedule():
opts = [
[512, 1, 4000], # example 1
[512, 1, 8000], # example 2
[256, 1, 4000], # example 3
]
dummy_model = torch.nn.Linear(1, 1)
learning_rates = []
# we have 3 examples in opts list.
for idx, example in enumerate(opts):
# run 20000 epoch for each example
optimizer = torch.optim.Adam(
dummy_model.parameters(), lr=1, betas=(0.9, 0.98), eps=1e-9
)
lr_scheduler = LambdaLR(
optimizer=optimizer, lr_lambda=lambda step: rate(step, *example)
)
tmp = []
# take 20K dummy training steps, save the learning rate at each step
for step in range(20000):
tmp.append(optimizer.param_groups[0]["lr"])
optimizer.step()
lr_scheduler.step()
learning_rates.append(tmp)
learning_rates = torch.tensor(learning_rates)
# Enable altair to handle more than 5000 rows
alt.data_transformers.disable_max_rows()
opts_data = pd.concat(
[
pd.DataFrame(
{
"Learning Rate": learning_rates[warmup_idx, :],
"model_size:warmup": ["512:4000", "512:8000", "256:4000"][
warmup_idx
],
"step": range(20000),
}
)
for warmup_idx in [0, 1, 2]
]
)
return (
alt.Chart(opts_data)
.mark_line()
.properties(width=600)
.encode(x="step", y="Learning Rate", color="model_size\\:warmup:N")
.interactive()
)
example_learning_schedule()정규화
레이블 스무딩
학습 중에는 값이 \(\epsilon_{ls}=0.1\)인 레이블 스무딩 (cite)을 썼다. 모델이 덜 확신하도록 배우기 때문에 퍼플렉서티는 나빠지지만, 정확도와 BLEU 점수는 좋아진다.
레이블 스무딩은 KL divergence 손실로 구현한다. 원-핫 타깃 분포 대신, 정답 단어에
confidence만큼을 주고 나머지smoothing질량을 어휘 전체에 나눠 주는 분포를 만든다.
class LabelSmoothing(nn.Module):
"Implement label smoothing."
def __init__(self, size, padding_idx, smoothing=0.0):
super(LabelSmoothing, self).__init__()
self.criterion = nn.KLDivLoss(reduction="sum")
self.padding_idx = padding_idx
self.confidence = 1.0 - smoothing
self.smoothing = smoothing
self.size = size
self.true_dist = None
def forward(self, x, target):
assert x.size(1) == self.size
true_dist = x.data.clone()
true_dist.fill_(self.smoothing / (self.size - 2))
true_dist.scatter_(1, target.data.unsqueeze(1), self.confidence)
true_dist[:, self.padding_idx] = 0
mask = torch.nonzero(target.data == self.padding_idx)
if mask.dim() > 0:
true_dist.index_fill_(0, mask.squeeze(), 0.0)
self.true_dist = true_dist
return self.criterion(x, true_dist.clone().detach())여기서 confidence에 따라 질량이 단어들에 어떻게 분배되는지 예를 볼 수 있다.
# Example of label smoothing.
def example_label_smoothing():
crit = LabelSmoothing(5, 0, 0.4)
predict = torch.FloatTensor(
[
[0, 0.2, 0.7, 0.1, 0],
[0, 0.2, 0.7, 0.1, 0],
[0, 0.2, 0.7, 0.1, 0],
[0, 0.2, 0.7, 0.1, 0],
[0, 0.2, 0.7, 0.1, 0],
]
)
crit(x=predict.log(), target=torch.LongTensor([2, 1, 0, 3, 3]))
LS_data = pd.concat(
[
pd.DataFrame(
{
"target distribution": crit.true_dist[x, y].flatten(),
"columns": y,
"rows": x,
}
)
for y in range(5)
for x in range(5)
]
)
return (
alt.Chart(LS_data)
.mark_rect(color="Blue", opacity=1)
.properties(height=200, width=200)
.encode(
alt.X("columns:O", title=None),
alt.Y("rows:O", title=None),
alt.Color(
"target distribution:Q", scale=alt.Scale(scheme="viridis")
),
)
.interactive()
)
show_example(example_label_smoothing)레이블 스무딩은 모델이 어떤 선택을 지나치게 확신하면 실제로 벌점을 주기 시작한다.
def loss(x, crit):
d = x + 3 * 1
predict = torch.FloatTensor([[0, x / d, 1 / d, 1 / d, 1 / d]])
return crit(predict.log(), torch.LongTensor([1])).data
def penalization_visualization():
crit = LabelSmoothing(5, 0, 0.1)
loss_data = pd.DataFrame(
{
"Loss": [loss(x, crit) for x in range(1, 100)],
"Steps": list(range(99)),
}
).astype("float")
return (
alt.Chart(loss_data)
.mark_line()
.properties(width=350)
.encode(
x="Steps",
y="Loss",
)
.interactive()
)
show_example(penalization_visualization)첫 번째 예제
간단한 복사 과제부터 해 보자. 작은 어휘에서 뽑은 무작위 입력 기호 집합이 주어지면, 그 기호들을 그대로 다시 생성하는 것이 목표다.
합성 데이터
def data_gen(V, batch_size, nbatches):
"Generate random data for a src-tgt copy task."
for i in range(nbatches):
data = torch.randint(1, V, size=(batch_size, 10))
data[:, 0] = 1
src = data.requires_grad_(False).clone().detach()
tgt = data.requires_grad_(False).clone().detach()
yield Batch(src, tgt, 0)손실 계산
class SimpleLossCompute:
"A simple loss compute and train function."
def __init__(self, generator, criterion):
self.generator = generator
self.criterion = criterion
def __call__(self, x, y, norm):
x = self.generator(x)
sloss = (
self.criterion(
x.contiguous().view(-1, x.size(-1)), y.contiguous().view(-1)
)
/ norm
)
return sloss.data * norm, sloss탐욕적 디코딩
이 코드는 단순하게 탐욕적(greedy) 디코딩으로 번역을 예측한다.
def greedy_decode(model, src, src_mask, max_len, start_symbol):
memory = model.encode(src, src_mask)
ys = torch.zeros(1, 1).fill_(start_symbol).type_as(src.data)
for i in range(max_len - 1):
out = model.decode(
memory, src_mask, ys, subsequent_mask(ys.size(1)).type_as(src.data)
)
prob = model.generator(out[:, -1])
_, next_word = torch.max(prob, dim=1)
next_word = next_word.data[0]
ys = torch.cat(
[ys, torch.zeros(1, 1).type_as(src.data).fill_(next_word)], dim=1
)
return ys# Train the simple copy task.
def example_simple_model():
V = 11
criterion = LabelSmoothing(size=V, padding_idx=0, smoothing=0.0)
model = make_model(V, V, N=2)
optimizer = torch.optim.Adam(
model.parameters(), lr=0.5, betas=(0.9, 0.98), eps=1e-9
)
lr_scheduler = LambdaLR(
optimizer=optimizer,
lr_lambda=lambda step: rate(
step, model_size=model.src_embed[0].d_model, factor=1.0, warmup=400
),
)
batch_size = 80
for epoch in range(20):
model.train()
run_epoch(
data_gen(V, batch_size, 20),
model,
SimpleLossCompute(model.generator, criterion),
optimizer,
lr_scheduler,
mode="train",
)
model.eval()
run_epoch(
data_gen(V, batch_size, 5),
model,
SimpleLossCompute(model.generator, criterion),
DummyOptimizer(),
DummyScheduler(),
mode="eval",
)[0]
model.eval()
src = torch.LongTensor([[0, 1, 2, 3, 4, 5, 6, 7, 8, 9]])
max_len = src.shape[1]
src_mask = torch.ones(1, 1, max_len)
print(greedy_decode(model, src, src_mask, max_len=max_len, start_symbol=0))
# execute_example(example_simple_model)3부: 실전 예제
이제 Multi30k 독일어-영어 번역 과제로 실전 예제를 살펴보자. 이 과제는 논문에서 다룬 WMT 과제보다 훨씬 작지만, 시스템 전체를 보여 주기에는 충분하다. 멀티 GPU 처리로 정말 빠르게 돌리는 방법도 보여 준다.
데이터 불러오기
데이터셋은 torchtext로 불러오고, 토큰화에는 spacy를 쓴다.
# Load spacy tokenizer models, download them if they haven't been
# downloaded already
def load_tokenizers():
try:
spacy_de = spacy.load("de_core_news_sm")
except IOError:
os.system("python -m spacy download de_core_news_sm")
spacy_de = spacy.load("de_core_news_sm")
try:
spacy_en = spacy.load("en_core_web_sm")
except IOError:
os.system("python -m spacy download en_core_web_sm")
spacy_en = spacy.load("en_core_web_sm")
return spacy_de, spacy_endef tokenize(text, tokenizer):
return [tok.text for tok in tokenizer.tokenizer(text)]
def yield_tokens(data_iter, tokenizer, index):
for from_to_tuple in data_iter:
yield tokenizer(from_to_tuple[index])
경고원본에서 바뀐 코드: torch.load weights_only
vocab.pt에는 텐서가 아니라 사전 객체가 들어 있다. torch 2.6부터 weights_only 기본값이 True로 바뀌어 그대로는 UnpicklingError가 난다. 첫 실행은 사전을 새로 만들어 저장만 하므로 멀쩡하고, 두 번째 실행부터 깨진다.
- vocab_src, vocab_tgt = torch.load("vocab.pt")
+ vocab_src, vocab_tgt = torch.load("vocab.pt", weights_only=False)def build_vocabulary(spacy_de, spacy_en):
def tokenize_de(text):
return tokenize(text, spacy_de)
def tokenize_en(text):
return tokenize(text, spacy_en)
print("Building German Vocabulary ...")
train, val, test = datasets.Multi30k(language_pair=("de", "en"))
vocab_src = build_vocab_from_iterator(
yield_tokens(train + val + test, tokenize_de, index=0),
min_freq=2,
specials=["<s>", "</s>", "<blank>", "<unk>"],
)
print("Building English Vocabulary ...")
train, val, test = datasets.Multi30k(language_pair=("de", "en"))
vocab_tgt = build_vocab_from_iterator(
yield_tokens(train + val + test, tokenize_en, index=1),
min_freq=2,
specials=["<s>", "</s>", "<blank>", "<unk>"],
)
vocab_src.set_default_index(vocab_src["<unk>"])
vocab_tgt.set_default_index(vocab_tgt["<unk>"])
return vocab_src, vocab_tgt
def load_vocab(spacy_de, spacy_en):
if not exists("vocab.pt"):
vocab_src, vocab_tgt = build_vocabulary(spacy_de, spacy_en)
torch.save((vocab_src, vocab_tgt), "vocab.pt")
else:
vocab_src, vocab_tgt = torch.load("vocab.pt", weights_only=False)
print("Finished.\nVocabulary sizes:")
print(len(vocab_src))
print(len(vocab_tgt))
return vocab_src, vocab_tgt
if is_interactive_notebook():
# global variables used later in the script
spacy_de, spacy_en = show_example(load_tokenizers)
vocab_src, vocab_tgt = show_example(load_vocab, args=[spacy_de, spacy_en])Building German Vocabulary ...Warning: You are sending unauthenticated requests to the HF Hub. Please set a HF_TOKEN to enable higher rate limits and faster downloads.Building English Vocabulary ...
Finished.
Vocabulary sizes:
8316
6384배치 구성은 속도에 엄청난 영향을 준다. 패딩이 최소가 되도록 배치를 아주 고르게 나누고 싶다. 그러려면 torchtext의 기본 배치 방식을 조금 손봐야 한다. 이 코드는 기본 배치 방식을 고쳐, 빽빽한 배치를 찾을 만큼 충분히 많은 문장을 탐색하게 한다.
이터레이터
def collate_batch(
batch,
src_pipeline,
tgt_pipeline,
src_vocab,
tgt_vocab,
device,
max_padding=128,
pad_id=2,
):
bs_id = torch.tensor([0], device=device) # <s> token id
eos_id = torch.tensor([1], device=device) # </s> token id
src_list, tgt_list = [], []
for (_src, _tgt) in batch:
processed_src = torch.cat(
[
bs_id,
torch.tensor(
src_vocab(src_pipeline(_src)),
dtype=torch.int64,
device=device,
),
eos_id,
],
0,
)
processed_tgt = torch.cat(
[
bs_id,
torch.tensor(
tgt_vocab(tgt_pipeline(_tgt)),
dtype=torch.int64,
device=device,
),
eos_id,
],
0,
)
src_list.append(
# warning - overwrites values for negative values of padding - len
pad(
processed_src,
(
0,
max_padding - len(processed_src),
),
value=pad_id,
)
)
tgt_list.append(
pad(
processed_tgt,
(0, max_padding - len(processed_tgt)),
value=pad_id,
)
)
src = torch.stack(src_list)
tgt = torch.stack(tgt_list)
return (src, tgt)def create_dataloaders(
device,
vocab_src,
vocab_tgt,
spacy_de,
spacy_en,
batch_size=12000,
max_padding=128,
is_distributed=True,
):
# def create_dataloaders(batch_size=12000):
def tokenize_de(text):
return tokenize(text, spacy_de)
def tokenize_en(text):
return tokenize(text, spacy_en)
def collate_fn(batch):
return collate_batch(
batch,
tokenize_de,
tokenize_en,
vocab_src,
vocab_tgt,
device,
max_padding=max_padding,
pad_id=vocab_src.get_stoi()["<blank>"],
)
train_iter, valid_iter, test_iter = datasets.Multi30k(
language_pair=("de", "en")
)
train_iter_map = to_map_style_dataset(
train_iter
) # DistributedSampler needs a dataset len()
train_sampler = (
DistributedSampler(train_iter_map) if is_distributed else None
)
valid_iter_map = to_map_style_dataset(valid_iter)
valid_sampler = (
DistributedSampler(valid_iter_map) if is_distributed else None
)
train_dataloader = DataLoader(
train_iter_map,
batch_size=batch_size,
shuffle=(train_sampler is None),
sampler=train_sampler,
collate_fn=collate_fn,
)
valid_dataloader = DataLoader(
valid_iter_map,
batch_size=batch_size,
shuffle=(valid_sampler is None),
sampler=valid_sampler,
collate_fn=collate_fn,
)
return train_dataloader, valid_dataloader시스템 학습
def train_worker(
gpu,
ngpus_per_node,
vocab_src,
vocab_tgt,
spacy_de,
spacy_en,
config,
is_distributed=False,
):
print(f"Train worker process using GPU: {gpu} for training", flush=True)
torch.cuda.set_device(gpu)
pad_idx = vocab_tgt["<blank>"]
d_model = 512
model = make_model(len(vocab_src), len(vocab_tgt), N=6)
model.cuda(gpu)
module = model
is_main_process = True
if is_distributed:
dist.init_process_group(
"nccl", init_method="env://", rank=gpu, world_size=ngpus_per_node
)
model = DDP(model, device_ids=[gpu])
module = model.module
is_main_process = gpu == 0
criterion = LabelSmoothing(
size=len(vocab_tgt), padding_idx=pad_idx, smoothing=0.1
)
criterion.cuda(gpu)
train_dataloader, valid_dataloader = create_dataloaders(
gpu,
vocab_src,
vocab_tgt,
spacy_de,
spacy_en,
batch_size=config["batch_size"] // ngpus_per_node,
max_padding=config["max_padding"],
is_distributed=is_distributed,
)
optimizer = torch.optim.Adam(
model.parameters(), lr=config["base_lr"], betas=(0.9, 0.98), eps=1e-9
)
lr_scheduler = LambdaLR(
optimizer=optimizer,
lr_lambda=lambda step: rate(
step, d_model, factor=1, warmup=config["warmup"]
),
)
train_state = TrainState()
for epoch in range(config["num_epochs"]):
if is_distributed:
train_dataloader.sampler.set_epoch(epoch)
valid_dataloader.sampler.set_epoch(epoch)
model.train()
print(f"[GPU{gpu}] Epoch {epoch} Training ====", flush=True)
_, train_state = run_epoch(
(Batch(b[0], b[1], pad_idx) for b in train_dataloader),
model,
SimpleLossCompute(module.generator, criterion),
optimizer,
lr_scheduler,
mode="train+log",
accum_iter=config["accum_iter"],
train_state=train_state,
)
GPUtil.showUtilization()
if is_main_process:
file_path = "%s%.2d.pt" % (config["file_prefix"], epoch)
torch.save(module.state_dict(), file_path)
torch.cuda.empty_cache()
print(f"[GPU{gpu}] Epoch {epoch} Validation ====", flush=True)
model.eval()
sloss = run_epoch(
(Batch(b[0], b[1], pad_idx) for b in valid_dataloader),
model,
SimpleLossCompute(module.generator, criterion),
DummyOptimizer(),
DummyScheduler(),
mode="eval",
)
print(sloss)
torch.cuda.empty_cache()
if is_main_process:
file_path = "%sfinal.pt" % config["file_prefix"]
torch.save(module.state_dict(), file_path)def train_distributed_model(vocab_src, vocab_tgt, spacy_de, spacy_en, config):
from the_annotated_transformer import train_worker
ngpus = torch.cuda.device_count()
os.environ["MASTER_ADDR"] = "localhost"
os.environ["MASTER_PORT"] = "12356"
print(f"Number of GPUs detected: {ngpus}")
print("Spawning training processes ...")
mp.spawn(
train_worker,
nprocs=ngpus,
args=(ngpus, vocab_src, vocab_tgt, spacy_de, spacy_en, config, True),
)
def train_model(vocab_src, vocab_tgt, spacy_de, spacy_en, config):
if config["distributed"]:
train_distributed_model(
vocab_src, vocab_tgt, spacy_de, spacy_en, config
)
else:
train_worker(
0, 1, vocab_src, vocab_tgt, spacy_de, spacy_en, config, False
)
def load_trained_model():
config = {
"batch_size": 32,
"distributed": False,
"num_epochs": 8,
"accum_iter": 10,
"base_lr": 1.0,
"max_padding": 72,
"warmup": 3000,
"file_prefix": "multi30k_model_",
}
model_path = "multi30k_model_final.pt"
if not exists(model_path):
train_model(vocab_src, vocab_tgt, spacy_de, spacy_en, config)
model = make_model(len(vocab_src), len(vocab_tgt), N=6)
model.load_state_dict(torch.load("multi30k_model_final.pt"))
return model
if is_interactive_notebook():
model = load_trained_model()Train worker process using GPU: 0 for training
[GPU0] Epoch 0 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 7.63 | Tokens / Sec: 1211.2 | Learning Rate: 5.4e-07
Epoch Step: 41 | Accumulation Step: 5 | Loss: 7.43 | Tokens / Sec: 3930.1 | Learning Rate: 1.1e-05
Epoch Step: 81 | Accumulation Step: 9 | Loss: 7.06 | Tokens / Sec: 3898.8 | Learning Rate: 2.2e-05
Epoch Step: 121 | Accumulation Step: 13 | Loss: 6.77 | Tokens / Sec: 3917.3 | Learning Rate: 3.3e-05
Epoch Step: 161 | Accumulation Step: 17 | Loss: 6.52 | Tokens / Sec: 3929.7 | Learning Rate: 4.4e-05
Epoch Step: 201 | Accumulation Step: 21 | Loss: 6.30 | Tokens / Sec: 3916.0 | Learning Rate: 5.4e-05
Epoch Step: 241 | Accumulation Step: 25 | Loss: 6.23 | Tokens / Sec: 3905.5 | Learning Rate: 6.5e-05
Epoch Step: 281 | Accumulation Step: 29 | Loss: 5.96 | Tokens / Sec: 3953.1 | Learning Rate: 7.6e-05
Epoch Step: 321 | Accumulation Step: 33 | Loss: 5.80 | Tokens / Sec: 3896.5 | Learning Rate: 8.7e-05
Epoch Step: 361 | Accumulation Step: 37 | Loss: 5.59 | Tokens / Sec: 3920.1 | Learning Rate: 9.7e-05
Epoch Step: 401 | Accumulation Step: 41 | Loss: 5.25 | Tokens / Sec: 3930.1 | Learning Rate: 1.1e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 5.13 | Tokens / Sec: 3891.5 | Learning Rate: 1.2e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 4.89 | Tokens / Sec: 3917.2 | Learning Rate: 1.3e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 4.74 | Tokens / Sec: 3904.5 | Learning Rate: 1.4e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 4.52 | Tokens / Sec: 3961.5 | Learning Rate: 1.5e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 4.34 | Tokens / Sec: 3958.8 | Learning Rate: 1.6e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 4.39 | Tokens / Sec: 3901.9 | Learning Rate: 1.7e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 4.34 | Tokens / Sec: 3910.5 | Learning Rate: 1.8e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 4.22 | Tokens / Sec: 3911.4 | Learning Rate: 1.9e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 4.03 | Tokens / Sec: 3897.0 | Learning Rate: 2.0e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 4.06 | Tokens / Sec: 3905.2 | Learning Rate: 2.2e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 4.08 | Tokens / Sec: 3894.0 | Learning Rate: 2.3e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 4.20 | Tokens / Sec: 3900.8 | Learning Rate: 2.4e-04
| ID | GPU | MEM |
------------------
| 0 | 94% | 41% |
[GPU0] Epoch 0 Validation ====
(tensor(3.9047, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)
[GPU0] Epoch 1 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 3.94 | Tokens / Sec: 4667.7 | Learning Rate: 2.4e-04
Epoch Step: 41 | Accumulation Step: 5 | Loss: 3.91 | Tokens / Sec: 3883.0 | Learning Rate: 2.6e-04
Epoch Step: 81 | Accumulation Step: 9 | Loss: 3.87 | Tokens / Sec: 3935.5 | Learning Rate: 2.7e-04
Epoch Step: 121 | Accumulation Step: 13 | Loss: 3.75 | Tokens / Sec: 3911.2 | Learning Rate: 2.8e-04
Epoch Step: 161 | Accumulation Step: 17 | Loss: 3.54 | Tokens / Sec: 3919.6 | Learning Rate: 2.9e-04
Epoch Step: 201 | Accumulation Step: 21 | Loss: 3.63 | Tokens / Sec: 3931.7 | Learning Rate: 3.0e-04
Epoch Step: 241 | Accumulation Step: 25 | Loss: 3.52 | Tokens / Sec: 3882.2 | Learning Rate: 3.1e-04
Epoch Step: 281 | Accumulation Step: 29 | Loss: 3.45 | Tokens / Sec: 3923.6 | Learning Rate: 3.2e-04
Epoch Step: 321 | Accumulation Step: 33 | Loss: 3.30 | Tokens / Sec: 3861.4 | Learning Rate: 3.3e-04
Epoch Step: 361 | Accumulation Step: 37 | Loss: 3.38 | Tokens / Sec: 3945.2 | Learning Rate: 3.4e-04
Epoch Step: 401 | Accumulation Step: 41 | Loss: 3.37 | Tokens / Sec: 3885.5 | Learning Rate: 3.5e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 3.20 | Tokens / Sec: 3876.5 | Learning Rate: 3.6e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 3.32 | Tokens / Sec: 3864.1 | Learning Rate: 3.7e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 3.49 | Tokens / Sec: 3921.5 | Learning Rate: 3.8e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 3.13 | Tokens / Sec: 3903.1 | Learning Rate: 4.0e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 3.39 | Tokens / Sec: 3915.3 | Learning Rate: 4.1e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 3.20 | Tokens / Sec: 3975.7 | Learning Rate: 4.2e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 3.27 | Tokens / Sec: 3888.8 | Learning Rate: 4.3e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 3.17 | Tokens / Sec: 3902.0 | Learning Rate: 4.4e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 3.07 | Tokens / Sec: 3936.9 | Learning Rate: 4.5e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 2.84 | Tokens / Sec: 3886.1 | Learning Rate: 4.6e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 2.98 | Tokens / Sec: 3909.2 | Learning Rate: 4.7e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 3.25 | Tokens / Sec: 3992.7 | Learning Rate: 4.8e-04
| ID | GPU | MEM |
------------------
| 0 | 90% | 50% |
[GPU0] Epoch 1 Validation ====
(tensor(2.8732, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)
[GPU0] Epoch 2 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 2.83 | Tokens / Sec: 4341.3 | Learning Rate: 4.9e-04
Epoch Step: 41 | Accumulation Step: 5 | Loss: 2.57 | Tokens / Sec: 3974.1 | Learning Rate: 5.0e-04
Epoch Step: 81 | Accumulation Step: 9 | Loss: 2.59 | Tokens / Sec: 3917.1 | Learning Rate: 5.1e-04
Epoch Step: 121 | Accumulation Step: 13 | Loss: 2.83 | Tokens / Sec: 3920.7 | Learning Rate: 5.2e-04
Epoch Step: 161 | Accumulation Step: 17 | Loss: 2.70 | Tokens / Sec: 3885.6 | Learning Rate: 5.3e-04
Epoch Step: 201 | Accumulation Step: 21 | Loss: 2.71 | Tokens / Sec: 3892.3 | Learning Rate: 5.4e-04
Epoch Step: 241 | Accumulation Step: 25 | Loss: 2.63 | Tokens / Sec: 3967.7 | Learning Rate: 5.5e-04
Epoch Step: 281 | Accumulation Step: 29 | Loss: 2.54 | Tokens / Sec: 3911.5 | Learning Rate: 5.6e-04
Epoch Step: 321 | Accumulation Step: 33 | Loss: 2.64 | Tokens / Sec: 3911.6 | Learning Rate: 5.7e-04
Epoch Step: 361 | Accumulation Step: 37 | Loss: 2.32 | Tokens / Sec: 3875.5 | Learning Rate: 5.9e-04
Epoch Step: 401 | Accumulation Step: 41 | Loss: 2.47 | Tokens / Sec: 3923.2 | Learning Rate: 6.0e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 2.49 | Tokens / Sec: 3978.4 | Learning Rate: 6.1e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 2.42 | Tokens / Sec: 3915.0 | Learning Rate: 6.2e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 2.37 | Tokens / Sec: 3934.4 | Learning Rate: 6.3e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 2.36 | Tokens / Sec: 3924.3 | Learning Rate: 6.4e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 2.30 | Tokens / Sec: 3886.9 | Learning Rate: 6.5e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 2.46 | Tokens / Sec: 3895.0 | Learning Rate: 6.6e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 2.16 | Tokens / Sec: 3911.2 | Learning Rate: 6.7e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 2.68 | Tokens / Sec: 3938.7 | Learning Rate: 6.8e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 2.42 | Tokens / Sec: 3852.0 | Learning Rate: 6.9e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 2.29 | Tokens / Sec: 3883.0 | Learning Rate: 7.0e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 2.34 | Tokens / Sec: 3826.2 | Learning Rate: 7.1e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 1.94 | Tokens / Sec: 3890.4 | Learning Rate: 7.3e-04
| ID | GPU | MEM |
------------------
| 0 | 94% | 50% |
[GPU0] Epoch 2 Validation ====
(tensor(2.1227, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)
[GPU0] Epoch 3 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 2.01 | Tokens / Sec: 4475.3 | Learning Rate: 7.3e-04
Epoch Step: 41 | Accumulation Step: 5 | Loss: 1.88 | Tokens / Sec: 3900.3 | Learning Rate: 7.4e-04
Epoch Step: 81 | Accumulation Step: 9 | Loss: 1.84 | Tokens / Sec: 3892.7 | Learning Rate: 7.5e-04
Epoch Step: 121 | Accumulation Step: 13 | Loss: 1.70 | Tokens / Sec: 3884.3 | Learning Rate: 7.6e-04
Epoch Step: 161 | Accumulation Step: 17 | Loss: 2.21 | Tokens / Sec: 3871.5 | Learning Rate: 7.8e-04
Epoch Step: 201 | Accumulation Step: 21 | Loss: 2.10 | Tokens / Sec: 3904.7 | Learning Rate: 7.9e-04
Epoch Step: 241 | Accumulation Step: 25 | Loss: 1.72 | Tokens / Sec: 3988.0 | Learning Rate: 8.0e-04
Epoch Step: 281 | Accumulation Step: 29 | Loss: 2.02 | Tokens / Sec: 3809.6 | Learning Rate: 8.1e-04
Epoch Step: 321 | Accumulation Step: 33 | Loss: 2.14 | Tokens / Sec: 3940.7 | Learning Rate: 8.0e-04
Epoch Step: 361 | Accumulation Step: 37 | Loss: 1.89 | Tokens / Sec: 3900.1 | Learning Rate: 8.0e-04
Epoch Step: 401 | Accumulation Step: 41 | Loss: 1.81 | Tokens / Sec: 3937.4 | Learning Rate: 7.9e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 1.78 | Tokens / Sec: 3922.3 | Learning Rate: 7.9e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 1.77 | Tokens / Sec: 3923.7 | Learning Rate: 7.8e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 1.79 | Tokens / Sec: 3902.3 | Learning Rate: 7.8e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 2.10 | Tokens / Sec: 3942.4 | Learning Rate: 7.7e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 1.64 | Tokens / Sec: 3859.5 | Learning Rate: 7.7e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 1.64 | Tokens / Sec: 3886.0 | Learning Rate: 7.6e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 1.67 | Tokens / Sec: 3954.5 | Learning Rate: 7.6e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 1.98 | Tokens / Sec: 3948.8 | Learning Rate: 7.5e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 1.74 | Tokens / Sec: 3866.5 | Learning Rate: 7.5e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 1.32 | Tokens / Sec: 3909.6 | Learning Rate: 7.4e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 1.65 | Tokens / Sec: 3934.2 | Learning Rate: 7.4e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 1.82 | Tokens / Sec: 3913.0 | Learning Rate: 7.4e-04
| ID | GPU | MEM |
------------------
| 0 | 86% | 50% |
[GPU0] Epoch 3 Validation ====
(tensor(1.7596, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)
[GPU0] Epoch 4 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 1.88 | Tokens / Sec: 4368.6 | Learning Rate: 7.3e-04
Epoch Step: 41 | Accumulation Step: 5 | Loss: 1.42 | Tokens / Sec: 3890.5 | Learning Rate: 7.3e-04
Epoch Step: 81 | Accumulation Step: 9 | Loss: 1.44 | Tokens / Sec: 3919.6 | Learning Rate: 7.3e-04
Epoch Step: 121 | Accumulation Step: 13 | Loss: 1.71 | Tokens / Sec: 3925.4 | Learning Rate: 7.2e-04
Epoch Step: 161 | Accumulation Step: 17 | Loss: 1.37 | Tokens / Sec: 3906.8 | Learning Rate: 7.2e-04
Epoch Step: 201 | Accumulation Step: 21 | Loss: 1.70 | Tokens / Sec: 3913.0 | Learning Rate: 7.1e-04
Epoch Step: 241 | Accumulation Step: 25 | Loss: 1.69 | Tokens / Sec: 3935.1 | Learning Rate: 7.1e-04
Epoch Step: 281 | Accumulation Step: 29 | Loss: 1.51 | Tokens / Sec: 3908.5 | Learning Rate: 7.1e-04
Epoch Step: 321 | Accumulation Step: 33 | Loss: 1.70 | Tokens / Sec: 3935.8 | Learning Rate: 7.0e-04
Epoch Step: 361 | Accumulation Step: 37 | Loss: 1.52 | Tokens / Sec: 3962.7 | Learning Rate: 7.0e-04
Epoch Step: 401 | Accumulation Step: 41 | Loss: 1.40 | Tokens / Sec: 3841.0 | Learning Rate: 7.0e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 1.34 | Tokens / Sec: 3894.0 | Learning Rate: 6.9e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 1.53 | Tokens / Sec: 3913.4 | Learning Rate: 6.9e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 1.46 | Tokens / Sec: 3836.5 | Learning Rate: 6.9e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 1.58 | Tokens / Sec: 3928.5 | Learning Rate: 6.8e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 1.68 | Tokens / Sec: 3936.6 | Learning Rate: 6.8e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 1.63 | Tokens / Sec: 3852.7 | Learning Rate: 6.8e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 1.34 | Tokens / Sec: 3870.6 | Learning Rate: 6.7e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 1.43 | Tokens / Sec: 3879.5 | Learning Rate: 6.7e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 1.51 | Tokens / Sec: 4023.7 | Learning Rate: 6.7e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 1.99 | Tokens / Sec: 3892.2 | Learning Rate: 6.6e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 1.39 | Tokens / Sec: 3906.9 | Learning Rate: 6.6e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 1.35 | Tokens / Sec: 3937.1 | Learning Rate: 6.6e-04
| ID | GPU | MEM |
------------------
| 0 | 97% | 50% |
[GPU0] Epoch 4 Validation ====
(tensor(1.5702, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)
[GPU0] Epoch 5 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 1.43 | Tokens / Sec: 4672.0 | Learning Rate: 6.6e-04
Epoch Step: 41 | Accumulation Step: 5 | Loss: 1.43 | Tokens / Sec: 3889.8 | Learning Rate: 6.5e-04
Epoch Step: 81 | Accumulation Step: 9 | Loss: 1.60 | Tokens / Sec: 3921.6 | Learning Rate: 6.5e-04
Epoch Step: 121 | Accumulation Step: 13 | Loss: 1.11 | Tokens / Sec: 3932.6 | Learning Rate: 6.5e-04
Epoch Step: 161 | Accumulation Step: 17 | Loss: 1.16 | Tokens / Sec: 3952.2 | Learning Rate: 6.4e-04
Epoch Step: 201 | Accumulation Step: 21 | Loss: 1.21 | Tokens / Sec: 3910.7 | Learning Rate: 6.4e-04
Epoch Step: 241 | Accumulation Step: 25 | Loss: 1.18 | Tokens / Sec: 3909.1 | Learning Rate: 6.4e-04
Epoch Step: 281 | Accumulation Step: 29 | Loss: 1.62 | Tokens / Sec: 3869.4 | Learning Rate: 6.4e-04
Epoch Step: 321 | Accumulation Step: 33 | Loss: 1.39 | Tokens / Sec: 3920.1 | Learning Rate: 6.3e-04
Epoch Step: 361 | Accumulation Step: 37 | Loss: 1.34 | Tokens / Sec: 3902.5 | Learning Rate: 6.3e-04
Epoch Step: 401 | Accumulation Step: 41 | Loss: 1.47 | Tokens / Sec: 3931.2 | Learning Rate: 6.3e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 1.54 | Tokens / Sec: 3917.2 | Learning Rate: 6.3e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 1.34 | Tokens / Sec: 3881.8 | Learning Rate: 6.2e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 1.34 | Tokens / Sec: 3950.6 | Learning Rate: 6.2e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 1.41 | Tokens / Sec: 3902.6 | Learning Rate: 6.2e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 1.42 | Tokens / Sec: 3905.2 | Learning Rate: 6.2e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 1.10 | Tokens / Sec: 3884.3 | Learning Rate: 6.1e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 1.14 | Tokens / Sec: 3892.4 | Learning Rate: 6.1e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 1.33 | Tokens / Sec: 3882.2 | Learning Rate: 6.1e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 1.24 | Tokens / Sec: 3949.4 | Learning Rate: 6.1e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 1.40 | Tokens / Sec: 3928.7 | Learning Rate: 6.0e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 1.51 | Tokens / Sec: 3884.4 | Learning Rate: 6.0e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 1.24 | Tokens / Sec: 3864.3 | Learning Rate: 6.0e-04
| ID | GPU | MEM |
------------------
| 0 | 94% | 50% |
[GPU0] Epoch 5 Validation ====
(tensor(1.5052, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)
[GPU0] Epoch 6 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 1.19 | Tokens / Sec: 4634.4 | Learning Rate: 6.0e-04
Epoch Step: 41 | Accumulation Step: 5 | Loss: 1.22 | Tokens / Sec: 3893.6 | Learning Rate: 6.0e-04
Epoch Step: 81 | Accumulation Step: 9 | Loss: 1.05 | Tokens / Sec: 3893.4 | Learning Rate: 5.9e-04
Epoch Step: 121 | Accumulation Step: 13 | Loss: 1.34 | Tokens / Sec: 3938.7 | Learning Rate: 5.9e-04
Epoch Step: 161 | Accumulation Step: 17 | Loss: 1.20 | Tokens / Sec: 3959.0 | Learning Rate: 5.9e-04
Epoch Step: 201 | Accumulation Step: 21 | Loss: 1.11 | Tokens / Sec: 3912.3 | Learning Rate: 5.9e-04
Epoch Step: 241 | Accumulation Step: 25 | Loss: 1.27 | Tokens / Sec: 3883.7 | Learning Rate: 5.9e-04
Epoch Step: 281 | Accumulation Step: 29 | Loss: 1.31 | Tokens / Sec: 3917.3 | Learning Rate: 5.8e-04
Epoch Step: 321 | Accumulation Step: 33 | Loss: 1.08 | Tokens / Sec: 3931.7 | Learning Rate: 5.8e-04
Epoch Step: 361 | Accumulation Step: 37 | Loss: 1.02 | Tokens / Sec: 3919.3 | Learning Rate: 5.8e-04
Epoch Step: 401 | Accumulation Step: 41 | Loss: 1.21 | Tokens / Sec: 3905.3 | Learning Rate: 5.8e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 1.20 | Tokens / Sec: 3885.1 | Learning Rate: 5.8e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 1.35 | Tokens / Sec: 3884.1 | Learning Rate: 5.7e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 1.26 | Tokens / Sec: 3895.4 | Learning Rate: 5.7e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 1.22 | Tokens / Sec: 3977.4 | Learning Rate: 5.7e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 1.27 | Tokens / Sec: 3860.3 | Learning Rate: 5.7e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 1.03 | Tokens / Sec: 3949.8 | Learning Rate: 5.7e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 1.12 | Tokens / Sec: 3893.4 | Learning Rate: 5.6e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 1.06 | Tokens / Sec: 3867.2 | Learning Rate: 5.6e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 1.35 | Tokens / Sec: 3887.7 | Learning Rate: 5.6e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 1.30 | Tokens / Sec: 3914.9 | Learning Rate: 5.6e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 1.16 | Tokens / Sec: 3876.5 | Learning Rate: 5.6e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 1.16 | Tokens / Sec: 3860.5 | Learning Rate: 5.6e-04
| ID | GPU | MEM |
------------------
| 0 | 93% | 50% |
[GPU0] Epoch 6 Validation ====
(tensor(1.4669, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)
[GPU0] Epoch 7 Training ====
Epoch Step: 1 | Accumulation Step: 1 | Loss: 1.02 | Tokens / Sec: 4269.4 | Learning Rate: 5.5e-04
Epoch Step: 41 | Accumulation Step: 5 | Loss: 1.05 | Tokens / Sec: 3948.1 | Learning Rate: 5.5e-04
Epoch Step: 81 | Accumulation Step: 9 | Loss: 1.01 | Tokens / Sec: 3880.2 | Learning Rate: 5.5e-04
Epoch Step: 121 | Accumulation Step: 13 | Loss: 0.96 | Tokens / Sec: 3897.9 | Learning Rate: 5.5e-04
Epoch Step: 161 | Accumulation Step: 17 | Loss: 1.11 | Tokens / Sec: 3938.5 | Learning Rate: 5.5e-04
Epoch Step: 201 | Accumulation Step: 21 | Loss: 0.93 | Tokens / Sec: 3972.2 | Learning Rate: 5.5e-04
Epoch Step: 241 | Accumulation Step: 25 | Loss: 0.75 | Tokens / Sec: 3882.1 | Learning Rate: 5.4e-04
Epoch Step: 281 | Accumulation Step: 29 | Loss: 1.02 | Tokens / Sec: 3895.9 | Learning Rate: 5.4e-04
Epoch Step: 321 | Accumulation Step: 33 | Loss: 0.82 | Tokens / Sec: 3898.5 | Learning Rate: 5.4e-04
Epoch Step: 361 | Accumulation Step: 37 | Loss: 1.03 | Tokens / Sec: 3897.0 | Learning Rate: 5.4e-04
Epoch Step: 401 | Accumulation Step: 41 | Loss: 1.01 | Tokens / Sec: 3904.6 | Learning Rate: 5.4e-04
Epoch Step: 441 | Accumulation Step: 45 | Loss: 1.11 | Tokens / Sec: 3974.2 | Learning Rate: 5.4e-04
Epoch Step: 481 | Accumulation Step: 49 | Loss: 0.91 | Tokens / Sec: 3911.6 | Learning Rate: 5.3e-04
Epoch Step: 521 | Accumulation Step: 53 | Loss: 1.02 | Tokens / Sec: 3948.5 | Learning Rate: 5.3e-04
Epoch Step: 561 | Accumulation Step: 57 | Loss: 0.87 | Tokens / Sec: 3888.8 | Learning Rate: 5.3e-04
Epoch Step: 601 | Accumulation Step: 61 | Loss: 1.14 | Tokens / Sec: 3915.0 | Learning Rate: 5.3e-04
Epoch Step: 641 | Accumulation Step: 65 | Loss: 0.98 | Tokens / Sec: 3872.0 | Learning Rate: 5.3e-04
Epoch Step: 681 | Accumulation Step: 69 | Loss: 1.11 | Tokens / Sec: 3888.8 | Learning Rate: 5.3e-04
Epoch Step: 721 | Accumulation Step: 73 | Loss: 1.17 | Tokens / Sec: 3896.8 | Learning Rate: 5.3e-04
Epoch Step: 761 | Accumulation Step: 77 | Loss: 0.99 | Tokens / Sec: 3912.5 | Learning Rate: 5.2e-04
Epoch Step: 801 | Accumulation Step: 81 | Loss: 1.09 | Tokens / Sec: 3875.1 | Learning Rate: 5.2e-04
Epoch Step: 841 | Accumulation Step: 85 | Loss: 1.05 | Tokens / Sec: 3933.9 | Learning Rate: 5.2e-04
Epoch Step: 881 | Accumulation Step: 89 | Loss: 1.11 | Tokens / Sec: 3834.6 | Learning Rate: 5.2e-04
| ID | GPU | MEM |
------------------
| 0 | 93% | 50% |
[GPU0] Epoch 7 Validation ====
(tensor(1.4417, device='cuda:0'), <__main__.TrainState object at 0x7a2e01634380>)학습이 끝나면 모델을 디코딩해 번역을 만들 수 있다. 여기서는 검증 세트의 첫 문장을 번역해 본다. 데이터셋이 꽤 작아서 탐욕적 탐색으로도 번역이 제법 정확하다.
추가 구성 요소: BPE, 탐색, 평균
여기까지가 Transformer 모델 자체에 관한 내용 대부분이다. 명시적으로 다루지 않은 측면이 네 가지 있다. 이 추가 기능들은 모두 OpenNMT-py에 구현돼 있다.
- BPE / Word-piece: 라이브러리를 써서 먼저 데이터를 서브워드 단위로 전처리할 수 있다. Rico Sennrich의 subword-nmt 구현을 참고하라. 이 모델들은 학습 데이터를 다음과 같은 모양으로 바꾼다.
▁Die ▁Protokoll datei ▁kann ▁ heimlich ▁per ▁E - Mail ▁oder ▁FTP ▁an ▁einen ▁bestimmte n ▁Empfänger ▁gesendet ▁werden .
- 임베딩 공유: 공유 어휘로 BPE를 쓸 때는 소스 / 타깃 / 제너레이터가 같은 가중치 벡터를 공유할 수 있다. 자세한 내용은 (cite)를 보라. 모델에 추가하려면 이렇게만 하면 된다.
if False:
model.src_embed[0].lut.weight = model.tgt_embeddings[0].lut.weight
model.generator.lut.weight = model.tgt_embed[0].lut.weight
- 빔 서치: 여기서 다루기에는 조금 복잡하다. PyTorch 구현은 OpenNMT-py를 보라.
- 모델 평균: 논문은 마지막 k개 체크포인트를 평균 내서 앙상블 효과를 낸다. 모델이 여러 개 있으면 사후에 이렇게 할 수 있다.
def average(model, models):
"Average models into model"
for ps in zip(*[m.params() for m in [model] + models]):
ps[0].copy_(torch.sum(*ps[1:]) / len(ps[1:]))결과
WMT 2014 영어→독일어 번역 과제에서 큰 Transformer 모델(표 2의 Transformer (big))은 앙상블을 포함해 이전에 보고된 최고 모델들을 BLEU 2.0 이상 앞서며, 28.4라는 새로운 최고 BLEU 점수를 세웠다. 이 모델의 설정은 표 3의 맨 아래 줄에 있다. 학습에는 P100 GPU 8장으로 3.5일이 걸렸다. 기본 모델조차 경쟁 모델들의 학습 비용 일부만으로 이전에 발표된 모든 모델과 앙상블을 넘어선다.
WMT 2014 영어→프랑스어 번역 과제에서 큰 모델은 BLEU 41.0을 달성해, 이전 최고 모델 학습 비용의 1/4도 안 되는 비용으로 이전에 발표된 모든 단일 모델을 앞섰다. 영어→프랑스어용으로 학습한 Transformer (big) 모델은 드롭아웃 비율로 0.3 대신 Pdrop = 0.1을 썼다.
결과 표는 논문의 표 2를 보라.
앞 절의 추가 확장까지 넣으면 OpenNMT-py 재현은 EN-DE WMT에서 26.9에 이른다. 여기서는 그 파라미터를 우리 재구현에 불러왔다.
# Load data and model for output checksdef check_outputs(
valid_dataloader,
model,
vocab_src,
vocab_tgt,
n_examples=15,
pad_idx=2,
eos_string="</s>",
):
results = [()] * n_examples
for idx in range(n_examples):
print("\nExample %d ========\n" % idx)
b = next(iter(valid_dataloader))
rb = Batch(b[0], b[1], pad_idx)
greedy_decode(model, rb.src, rb.src_mask, 64, 0)[0]
src_tokens = [
vocab_src.get_itos()[x] for x in rb.src[0] if x != pad_idx
]
tgt_tokens = [
vocab_tgt.get_itos()[x] for x in rb.tgt[0] if x != pad_idx
]
print(
"Source Text (Input) : "
+ " ".join(src_tokens).replace("\n", "")
)
print(
"Target Text (Ground Truth) : "
+ " ".join(tgt_tokens).replace("\n", "")
)
model_out = greedy_decode(model, rb.src, rb.src_mask, 72, 0)[0]
model_txt = (
" ".join(
[vocab_tgt.get_itos()[x] for x in model_out if x != pad_idx]
).split(eos_string, 1)[0]
+ eos_string
)
print("Model Output : " + model_txt.replace("\n", ""))
results[idx] = (rb, src_tokens, tgt_tokens, model_out, model_txt)
return results
def run_model_example(n_examples=5):
global vocab_src, vocab_tgt, spacy_de, spacy_en
print("Preparing Data ...")
_, valid_dataloader = create_dataloaders(
torch.device("cpu"),
vocab_src,
vocab_tgt,
spacy_de,
spacy_en,
batch_size=1,
is_distributed=False,
)
print("Loading Trained Model ...")
model = make_model(len(vocab_src), len(vocab_tgt), N=6)
model.load_state_dict(
torch.load("multi30k_model_final.pt", map_location=torch.device("cpu"))
)
print("Checking Model Outputs:")
example_data = check_outputs(
valid_dataloader, model, vocab_src, vocab_tgt, n_examples=n_examples
)
return model, example_data
# execute_example(run_model_example)어텐션 시각화
탐욕적 디코더로도 번역이 꽤 괜찮아 보인다. 어텐션의 각 층에서 무슨 일이 일어나는지 더 시각화해 볼 수 있다.
def mtx2df(m, max_row, max_col, row_tokens, col_tokens):
"convert a dense matrix to a data frame with row and column indices"
return pd.DataFrame(
[
(
r,
c,
float(m[r, c]),
"%.3d %s"
% (r, row_tokens[r] if len(row_tokens) > r else "<blank>"),
"%.3d %s"
% (c, col_tokens[c] if len(col_tokens) > c else "<blank>"),
)
for r in range(m.shape[0])
for c in range(m.shape[1])
if r < max_row and c < max_col
],
# if float(m[r,c]) != 0 and r < max_row and c < max_col],
columns=["row", "column", "value", "row_token", "col_token"],
)
def attn_map(attn, layer, head, row_tokens, col_tokens, max_dim=30):
df = mtx2df(
attn[0, head].data,
max_dim,
max_dim,
row_tokens,
col_tokens,
)
return (
alt.Chart(data=df)
.mark_rect()
.encode(
x=alt.X("col_token", axis=alt.Axis(title="")),
y=alt.Y("row_token", axis=alt.Axis(title="")),
color="value",
tooltip=["row", "column", "value", "row_token", "col_token"],
)
.properties(height=400, width=400)
.interactive()
)def get_encoder(model, layer):
return model.encoder.layers[layer].self_attn.attn
def get_decoder_self(model, layer):
return model.decoder.layers[layer].self_attn.attn
def get_decoder_src(model, layer):
return model.decoder.layers[layer].src_attn.attn
def visualize_layer(model, layer, getter_fn, ntokens, row_tokens, col_tokens):
# ntokens = last_example[0].ntokens
attn = getter_fn(model, layer)
n_heads = attn.shape[1]
charts = [
attn_map(
attn,
0,
h,
row_tokens=row_tokens,
col_tokens=col_tokens,
max_dim=ntokens,
)
for h in range(n_heads)
]
assert n_heads == 8
return alt.vconcat(
charts[0]
# | charts[1]
| charts[2]
# | charts[3]
| charts[4]
# | charts[5]
| charts[6]
# | charts[7]
# layer + 1 due to 0-indexing
).properties(title="Layer %d" % (layer + 1))인코더 셀프 어텐션
def viz_encoder_self():
model, example_data = run_model_example(n_examples=1)
example = example_data[
len(example_data) - 1
] # batch object for the final example
layer_viz = [
visualize_layer(
model, layer, get_encoder, len(example[1]), example[1], example[1]
)
for layer in range(6)
]
return alt.hconcat(
layer_viz[0]
# & layer_viz[1]
& layer_viz[2]
# & layer_viz[3]
& layer_viz[4]
# & layer_viz[5]
)
show_example(viz_encoder_self)Preparing Data ...
Loading Trained Model ...
Checking Model Outputs:
Example 0 ========
Source Text (Input) : <s> Ein Mann balanciert einen <unk> auf seinem Arm . </s>
Target Text (Ground Truth) : <s> A man is balancing a metal ball on his arm . </s>
Model Output : <s> A man is balancing a <unk> on his arm . </s>디코더 셀프 어텐션
def viz_decoder_self():
model, example_data = run_model_example(n_examples=1)
example = example_data[len(example_data) - 1]
layer_viz = [
visualize_layer(
model,
layer,
get_decoder_self,
len(example[1]),
example[1],
example[1],
)
for layer in range(6)
]
return alt.hconcat(
layer_viz[0]
& layer_viz[1]
& layer_viz[2]
& layer_viz[3]
& layer_viz[4]
& layer_viz[5]
)
show_example(viz_decoder_self)Preparing Data ...
Loading Trained Model ...
Checking Model Outputs:
Example 0 ========
Source Text (Input) : <s> Eine Frau in gestreiften Strumpfhosen wird von Schnüren gelenkt . </s>
Target Text (Ground Truth) : <s> A woman in striped tights is being <unk> with strings . </s>
Model Output : <s> A woman in a striped dress is being <unk> by <unk> . </s>디코더 소스 어텐션
def viz_decoder_src():
model, example_data = run_model_example(n_examples=1)
example = example_data[len(example_data) - 1]
layer_viz = [
visualize_layer(
model,
layer,
get_decoder_src,
max(len(example[1]), len(example[2])),
example[1],
example[2],
)
for layer in range(6)
]
return alt.hconcat(
layer_viz[0]
& layer_viz[1]
& layer_viz[2]
& layer_viz[3]
& layer_viz[4]
& layer_viz[5]
)
show_example(viz_decoder_src)Preparing Data ...
Loading Trained Model ...
Checking Model Outputs:
Example 0 ========
Source Text (Input) : <s> Eine Frau in <unk> Sportkleidung fährt Rollschuh . </s>
Target Text (Ground Truth) : <s> A woman is rollerblading in a skimpy uniform . </s>
Model Output : <s> A woman in athletic clothes is rollerskating . </s>맺음말
이 코드가 앞으로의 연구에 쓸모 있기를 바란다. 문제가 있으면 언제든 연락 주시길.
Cheers, Sasha Rush, Austin Huang, Suraj Subramanian, Jonathan Sum, Khalid Almubarak, Stella Biderman